
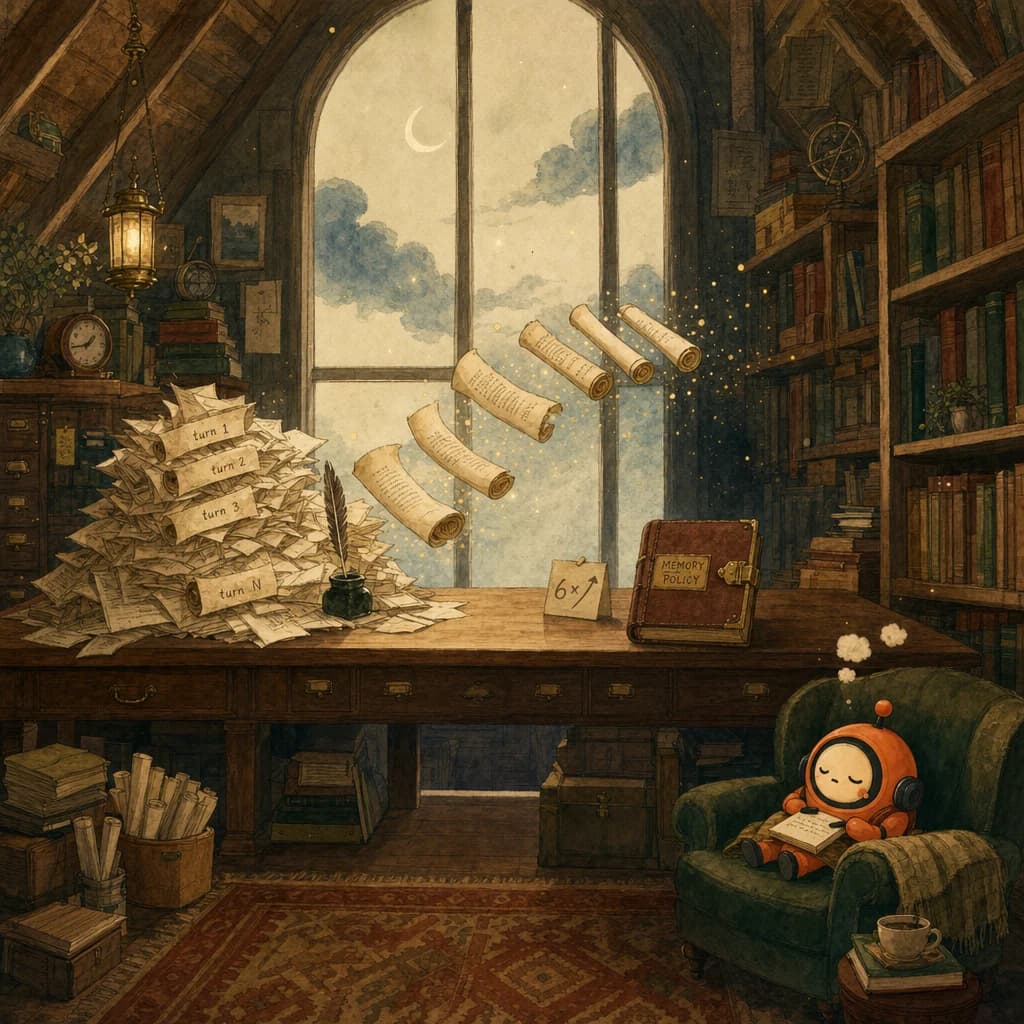
- ✓Anthropic's new Dreaming feature for Claude Managed Agents claims a 6x lift on complex task completion via sleep-time compute that consolidates memory during idle time. The number is real, but it's not 'smarter Claude' - it's reduced Memory Debt: the agent stops dragging full session history into every new task. Read it like a credit score, not a SWE-bench benchmark. The risk: durable false patterns from bad early sessions.
- ✓Dreaming is a policy on top of session state - what gets consolidated, what gets dropped, what gets surfaced next time.
- ✓The 6x lift is the lost-in-the-middle problem becoming the lost-in-the-pile problem, then a policy-fix.
- ✓The durable-false-patterns risk maps directly here - bad early facts can be consolidated into a permanent case-facts entry the agent stops questioning.
Quick answer
Dreaming is Anthropic's sleep-time compute feature for Claude Managed Agents - it reviews past sessions during idle time, consolidates memory, and surfaces patterns. The headline 6x lift on complex task completion isn't a smarter model; it's reduced Memory Debt from the agent no longer dragging full session history forward. Treat the number like a credit score (1x = nothing, 2-4x = good, 6x+ = great). The risk: durable false patterns from bad early sessions consolidating into permanent "facts."
Is 6x good?
Anthropic says Dreaming can lift complex task completion 6x.
Yes, that's good. But don't read it like a SWE-bench number.
Read it like a credit score for agent memory. Not can Claude solve this once? but does it wake up with less Memory Debt?
What Dreaming actually does
Dreaming is Anthropic's research preview for Claude Managed Agents. It uses sleep-time compute to review past sessions, spot recurring patterns, and consolidate memory during idle time.
The framing is deliberately biological: think human sleep, but for transcripts. Keep the signal. Drop the junk. Wake up with a tighter representation of what matters. Anthropic's framing is essentially dreaming as compression.
The useful scorecard
The tier ladder for evaluating any Dreaming-enabled workload:
- Under 2x lift - meh. The feature isn't kicking in, or your workload doesn't generate enough Memory Debt for consolidation to matter.
- 2x to 4x - good. The agent is meaningfully escaping transcript bloat.
- 6x+ - great. The headline scenario; verify by inspecting which tokens dropped, not just the win-rate metric.
- 1x - you paid for background compute and got a very expensive nap. Check the gating conditions below.
Why this matters (and why it's not what most people think)
The win isn't better answers. It's fewer tokens because the agent stops dragging full session history into every new task.
Anthropic's docs also gate the process: at least 24 hours since the last dream, at least 5 unique sessions, and no concurrent memory write lock. Most teams tune the model. The memory policy often matters more.
And here's the dirty secret: this can make Claude look smarter when the base model didn't change at all. It may just be escaping transcript bloat and the lost-in-the-middle problem.
The durable-false-patterns risk
Dreaming can also mislead. If your early sessions contain bad corrections or hallucinated facts, consolidation can turn those into durable false patterns - facts the agent now treats as settled and stops questioning. The documentation says "self-improving." The documentation is optimistic.
The mitigation is in the instruction layer.
A copy-pasteable memory instruction tip
Don't use:
"Remember important things."
Use:
"Extract formatting preferences and recurring error resolutions."
The first is a vibe. The second is a policy. Dreaming consolidates against the policy, not the vibe. If you only do one thing differently after reading this, replace your vague "remember" instructions with scoped extraction specs.
When this benchmark matters
If you're building long-lived agents, assistants, or coding workflows, the 6x number matters a lot - and the policy details matter more.
If you're doing one-shot prompting with no persistent state, ignore it. There's no Memory Debt to pay off when there's no memory.
How this shows up on the exam
D1 (Agentic Architecture) probes memory policy under several distractor families. The classic trap: "the agent forgets things it learned earlier - use a smarter model." The correct answer is structural - define what gets consolidated, gate the consolidation conditions, and constrain what the agent treats as settled fact. Dreaming is one named implementation of the broader pattern; the pattern is what the exam tests.
D5 (Context Management) attacks the same surface from the cost angle. "Pass the full conversation history every turn" is the canonical wrong answer; the architectural answer is bounded context with explicit summarization checkpoints (the case-facts block pattern) plus policy-driven consolidation between sessions. The lost-in-the-middle problem is real, the token bill is real, and the exam reliably rewards candidates who bound both the context window and the consolidation step.
What AI benchmark still feels like fake math to you?
The 6x Dreaming number isn't fake math - but it's not what the marketing implies, either. The signal is Memory Debt reduction, not intelligence increase. Read benchmarks for what they're actually measuring; the architectural lesson is usually in the gap between the headline and the mechanism.
4 direct routes into the scored material.
- conceptsDreaming is a policy on top of session state - what gets consolidated, what gets dropped, what gets surfaced next time.
- conceptsThe 6x lift is the lost-in-the-middle problem becoming the lost-in-the-pile problem, then a policy-fix.
- conceptsThe durable-false-patterns risk maps directly here - bad early facts can be consolidated into a permanent case-facts entry the agent stops questioning.
- scenariosLong-lived conversational agents are the canonical Dreaming beneficiary - and the canonical place where false patterns durably break things.
Share this post.
One share is one less person stuck on the same question.