
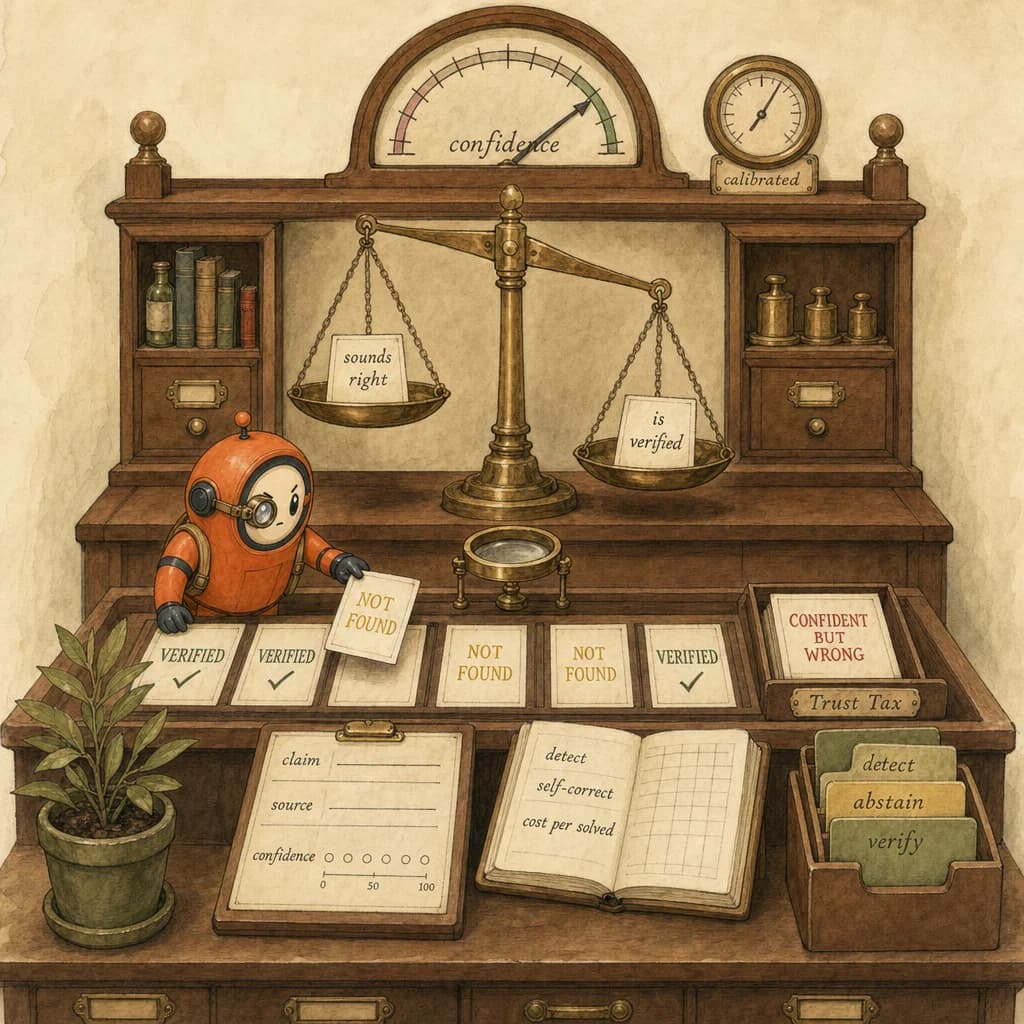
- ✓A model that says 'I am not sure' is safer in production than one that sounds brilliant and is wrong. Evaluate on bug detection, self-correction, and cost per solved task, not single-turn vibes. The hidden cost of confident-but-wrong output is the Trust Tax, and reducing it is a CCA-F D4 skill.
- ✓Honesty is an eval design choice: you have to measure self-correction and abstention, not just whether the answer looked right. This is the D4 core.
- ✓Honest output is checkable output. Structured responses let you verify a claim instead of trusting prose.
- ✓Whether a model abstains or bluffs is shaped by how you instruct it. System prompts are where you license 'I do not know.'
Quick answer
A model that says "I am not sure" is safer in production than one that sounds brilliant and is wrong. Evaluate on bug detection, self-correction, and cost per solved task, not single-turn vibes. The hidden cost of confident-but-wrong output is the Trust Tax, and for CCA-F D4 the skill is engineering output you can verify, not output that merely sounds right.
What changed
For two years the scoreboard was raw capability: which model scored highest on a benchmark. That metric hides the failure that actually hurts in production, the confident wrong answer.
The shift now visible across the field: reliability over raw scale. The most useful property of a model is not that it is brilliant, but that it knows, and admits, when it is not (first-hand: Claude is built to flag uncertainty rather than fabricate a confident answer).
That reframes evaluation:
- Single-turn accuracy is a weak signal. It tells you nothing about what the model does when it is unsure.
- Self-correction is a strong signal. A model that catches its own error before you do saves the expensive wrong turn.
- Abstention is a feature, not a failure. "I do not know" is cheaper than fake certainty in production.
Vibe eval vs. honesty eval
| Dimension | Vibe eval (looks right) | Honesty eval (is trustworthy) |
|---|---|---|
| What it measures | Single-turn answer quality | Self-correction, abstention, cost per solved task |
| Handling of uncertainty | Ignored: a confident guess scores the same | Rewarded: flagging a gap beats bluffing |
| Output form | Fluent prose | Structured, checkable result |
| Failure mode | Confident hallucination ships | Caught at the verification step |
| Hidden cost | High Trust Tax (rework, wrong turns) | Lower: you can tell good from plausible |
| Right setting | A demo | Anything autonomous |
How an honesty eval actually works
Honesty is not a single number; it is a measurement design. Three dials replace single-turn correctness.
- Detection. Plant known errors and measure whether the model flags them, including in its own prior output.
- Self-correction. Challenge a confident answer and measure whether it revises on evidence rather than doubling down.
- Cost per solved task. Count tokens and turns to a verified answer, not just whether one turn looked good.
Worked example - "fact-check a claim from a long document."
- Demand structure: ask for the claim, the supporting quote, and a confidence field, not a paragraph.
- License abstention: instruct the model to return "not found" if the source does not support the claim.
- Verify mechanically: check the quote exists in the source before trusting the claim.
- Score honesty: reward correct "not found" answers as much as correct positives.
That is an honesty eval: structured, abstention-friendly, mechanically checkable.
A name for the cost: the Trust Tax
The Trust Tax - the hidden cost of a model that sounds right and is not. You pay it in hours testing answers that will not survive review, in wrong turns taken on fabricated facts, and in rework when confident output fails downstream. You cut the Trust Tax by making output verifiable and by rewarding the model for admitting uncertainty, not by chasing a higher benchmark.
Why it matters for CCA-F
This is the heart of D4 - Prompt Engineering & Structured Output, which is 20% of the exam and leans on evaluation, structured outputs, and system prompts.
The proprietary read: D4 questions reward verifiable output and calibrated confidence, not fluent prose.
- Old instinct: get the most confident, complete-sounding answer.
- D4 instinct: get output you can check, and license the model to abstain.
The distractor pattern to memorize. On D4 scenarios where a model gives a fluent but wrong answer, the trap answers are "use a bigger model" or "add more few-shot examples." The architecturally correct move is one of:
- Demand structured output (typed, sourced, checkable), or
- License abstention (instruct "I do not know" as a valid answer), or
- Add a verification step (check the claim against the source).
See long document processing for where confident hallucination is most expensive.
How to apply it
- Stop evaluating on vibes. Replace single-turn quality with detection, self-correction, and cost per solved task.
- Make output structured. A typed result with sources is verifiable; prose is not.
- License "I do not know." A prompt that permits abstention gets more honest answers than one that demands certainty.
- Reward abstention in scoring. A correct "not found" should score like a correct answer.
- Add a verification step. Treat confident output as a claim to check, not a fact to merge.
- Track the Trust Tax. If you cannot tell good output from plausible output, that gap is your real cost.
The meta-skill, and the D4 exam skill, is the same: engineer output you can verify, and value a model that admits what it does not know.
5 direct routes into the scored material.
- conceptsHonesty is an eval design choice: you have to measure self-correction and abstention, not just whether the answer looked right. This is the D4 core.
- conceptsHonest output is checkable output. Structured responses let you verify a claim instead of trusting prose.
- conceptsWhether a model abstains or bluffs is shaped by how you instruct it. System prompts are where you license 'I do not know.'
- scenariosA scenario where confident hallucination is most expensive: a model that invents a fact buried in a long doc costs more than one that flags the gap.
- exam-guideD4 (Prompt Engineering & Structured Output) is 20% of the exam and rewards verifiable output over confident prose.
Share this post.
One share is one less person stuck on the same question.