
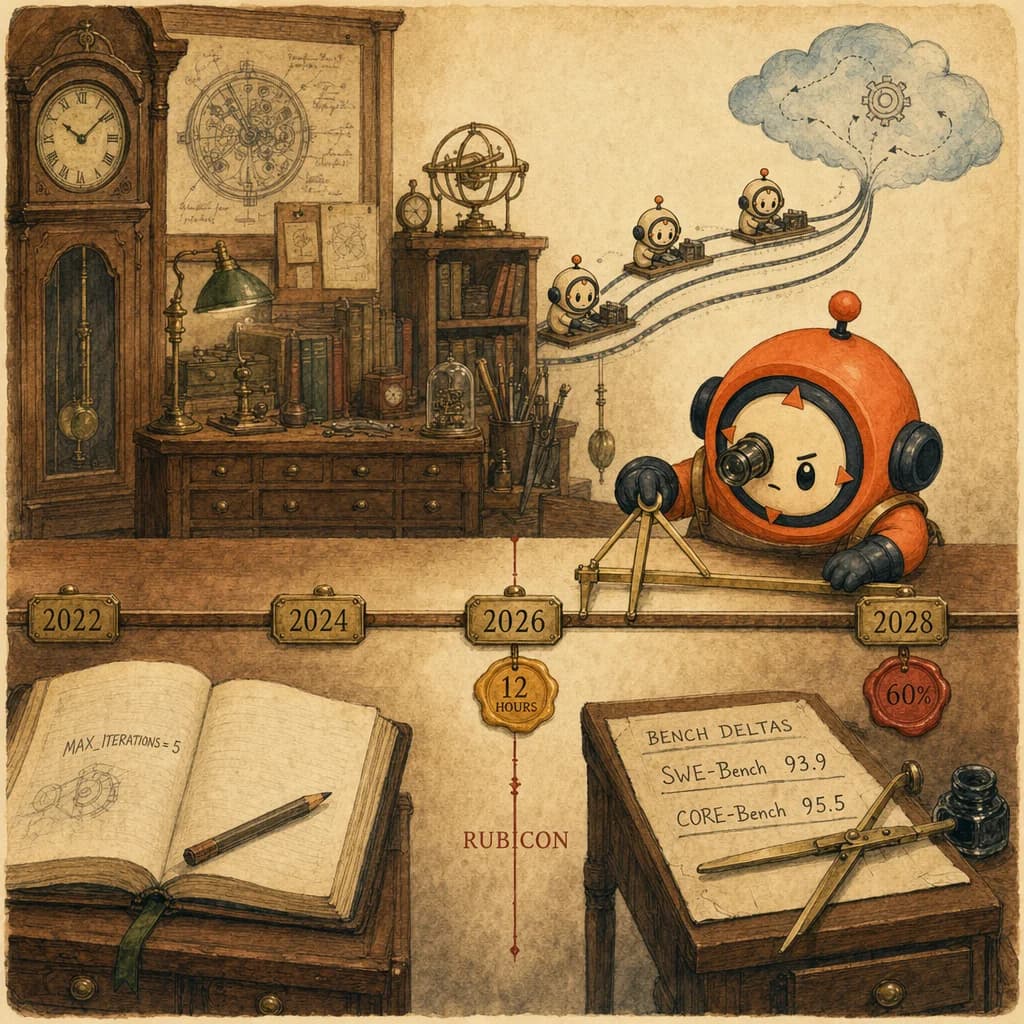
- ✓Anthropic co-founder Jack Clark gives 60% odds that AI systems will autonomously build their own successor models by end of 2028. Sustained agentic execution went from seconds in 2022 to ~12 hours in 2026. Anthropic models post 93.9% on SWE-Bench Verified and 95.5% on CORE-Bench. The nearer-term risk is not movie-villain AI; it is competent subagents quietly changing org design before governance catches up.
- ✓Sustained agentic execution (seconds to 12 hours) is the concept this prediction is built on. The agentic-loops page is the architectural primitive.
- ✓SWE-Bench Verified at 93.9% and CORE-Bench at 95.5% are the benchmark-creep evidence. Evaluation discipline is what keeps these numbers meaningful.
- ✓Automated AI R&D is the multi-agent research scenario at frontier-lab scale. The architecture patterns transfer down to production teams.
Quick answer
Anthropic co-founder Jack Clark gives 60% odds that AI systems will autonomously build their own successor models by end of 2028. Sustained agentic execution went from seconds in 2022 to ~12 hours now. Anthropic models post 93.9% on SWE-Bench Verified and 95.5% on CORE-Bench. The nearer-term risk is not movie-villain AI; it is competent subagents quietly changing org design before governance catches up. Track autonomy frontier, not chatbot vibes.
60% by 2028. Your roadmap is not ready.
Ten quick notes on Anthropic co-founder Jack Clark's automated AI R&D warning. The signal is worth stitching together. Most coverage skips the operational implications.
10 notes worth keeping
1. Start with the number
Clark puts a 60% chance on AI systems building their successor models by end of 2028. That is a planning horizon, not science fiction. Roadmaps that do not reflect this probability are roadmaps for the world Clark thinks has a 40% chance of happening.
2. Translate "Rubicon" correctly
AI R&D stops being human-guided and becomes human-optional. A different risk class entirely. The transition is not gradual; it is a phase change. One day the system needs a human to pick the next experiment. The day after, it does not.
3. Track autonomy, not vibes
Most people watch chatbot vibes (the latest hot take on the latest model release). The signal that actually matters is sustained execution: how long an agent can work on a single task without human intervention. Seconds in 2022. ~12 hours now. The leading indicator is when this number crosses into multi-day runs that produce verifiable artifacts.
4. Benchmark creep matters more than hot takes
Anthropic models post 93.9% on SWE-Bench Verified and 95.5% on CORE-Bench. Those are software-engineering and reasoning benchmarks where headroom is shrinking. When a benchmark designed to be hard becomes routine, the underlying capability has moved. Track the benchmark deltas, not the marketing posts.
5. Cap recursive loops
If you are testing agentic workflows, cap max_iterations. The new Outcomes flow can self-grade and iterate; without a cap it will burn credits fast. After Anthropic Agent SDK's June 15, 2026 programmatic-credits switch, that burn shows up on your invoice. max_iterations=5 to 10 is the cheap insurance. Forgetting it is the expensive mistake.
6. Use /goal for long-horizon work
Most people prompt step by step. /goal works better for long tasks because you define the end state, not every move. The agent picks the path. Your job becomes specifying what done looks like, not narrating each step.
7. Do not confuse Agent View with Managed Agents
Agent View is the local workflow UI. Managed Agents is production infrastructure that Anthropic runs for you with managed credits, retries, and observability. They sound similar; they are completely different products. Confusing them is expensive, especially around credit metering. Read the docs for the one you actually have.
8. The leadership-relevant signal
Society and frontier labs are not prepared for an intelligence explosion if the handoff happens fast. Clark says this himself. The prep work is mostly slow institutional change: governance frameworks, board-level autonomy metrics, audit access (see the Mythos restriction post for the closest worked example). Start before the headlines force the conversation.
9. The realistic near-term risk
It is not movie-villain AI. The realistic risk is competent subagents quietly changing org design before governance catches up. An agent that drafts plans, schedules meetings, and writes OKRs is not unsafe in any classical sense. It is just operating faster than the human governance process. Decisions get made before the org chart knows who decided them. That is the governance gap to close first.
10. Add one board metric this quarter
Percent of R&D work that can run without human intervention for 1, 6, and 12 hours. Today this is probably under 20% for the 1-hour band and near zero for the 12-hour band. By end of 2027 those numbers will be materially higher. Boards that track the metric see the curve coming. Boards that wait for the headlines govern in reactive mode.
The bonus tip most people miss
Anthropic's actual control point is not the model. It is orchestration, success criteria, and budget caps. That is where preparedness actually lives. Teams optimising the model selection are optimising the wrong layer. The layer that controls the autonomy frontier is the orchestration layer above the model.
How this shows up on the exam
D1 (Agentic Architecture, 27%) consistently tests sustained-execution patterns: how to structure an agent loop that runs for hours without human intervention while preserving quality. Questions in this family ask about iteration caps, termination conditions, error handling for long-running loops, and recovery from partial failure. The exam reliably rewards architectural answers that bound the loop (max_iterations, explicit success criteria, escalation triggers) over answers that trust the loop (rely on the model to know when to stop). Clark's "Rubicon" framing is the policy-level expression of this engineering pattern.
D5 (Context Management, 15%) tests sustained-execution from the cost and reliability angle. A 12-hour agentic run requires deliberate context budgeting, state checkpointing, and memory consolidation policies. The lost-in-the-middle problem is real at this scale. The exam-correct answer is structural: explicit summarisation checkpoints (the case-facts block pattern), bounded context windows, and policy-driven consolidation between phases. Without these, the long-running agent degrades in quality before it terminates.
Which of these ten was new to you?
The signal worth asking your team about: which one of these you would action this quarter, and which would wait for 2027. The honest answer for most teams is the iteration cap and the board metric should land now; everything else can sequence. The 60% is the number. The work is what comes after the number.
4 direct routes into the scored material.
- conceptsSustained agentic execution (seconds to 12 hours) is the concept this prediction is built on. The agentic-loops page is the architectural primitive.
- conceptsSWE-Bench Verified at 93.9% and CORE-Bench at 95.5% are the benchmark-creep evidence. Evaluation discipline is what keeps these numbers meaningful.
- scenariosAutomated AI R&D is the multi-agent research scenario at frontier-lab scale. The architecture patterns transfer down to production teams.
- scenariosThe competent-subagent governance risk maps to ops surfaces first: agents quietly changing process before review catches up.
Share this post.
One share is one less person stuck on the same question.