
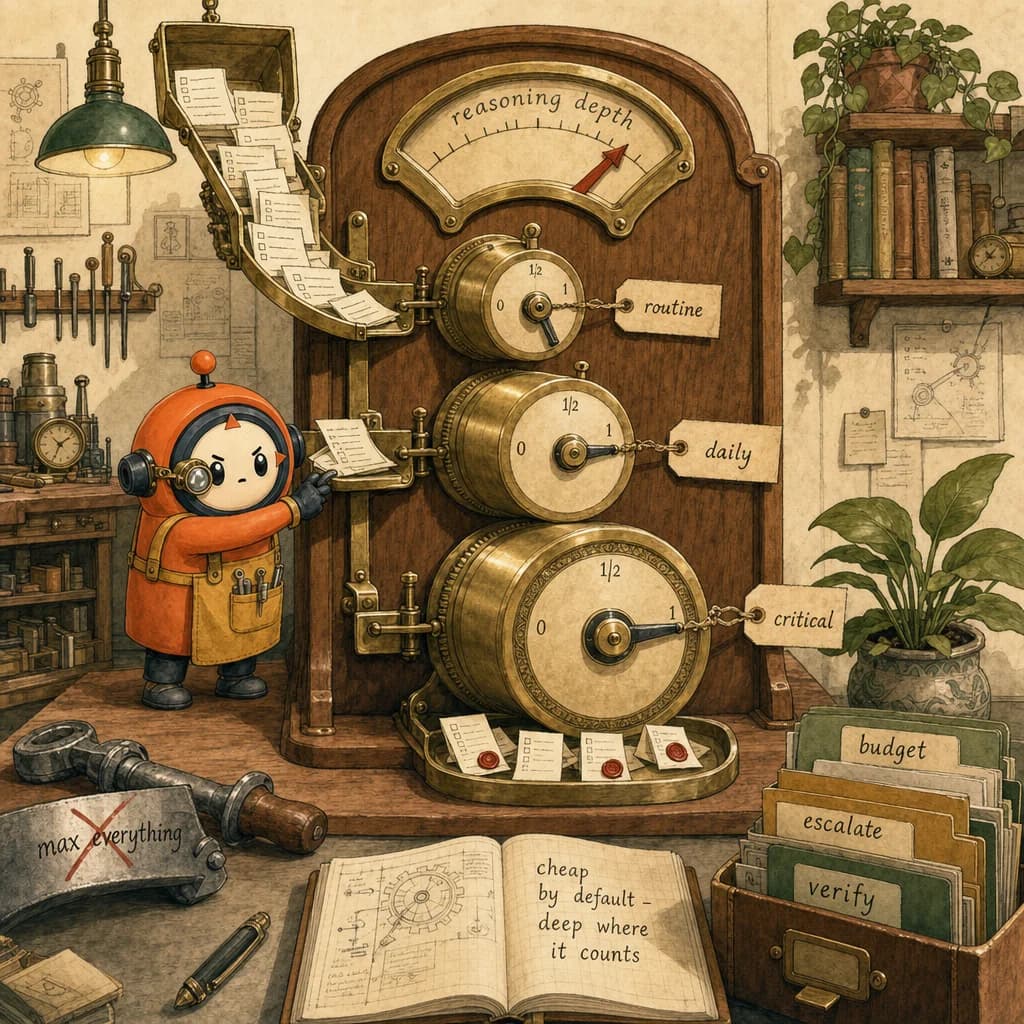
- ✓A thinking-budget policy is a written rule for how much reasoning each task gets: fast and shallow for simple work, deep and slow for accuracy-critical work. Once reasoning effort is a knob, picking one default setting for everything wastes money on easy tasks and under-thinks the hard ones. Allocating reasoning depth to task difficulty is a CCA-F D4 skill.
- ✓Plan mode is the clearest place reasoning effort pays for itself: think before acting on hard work, skip it on trivial edits.
- ✓How you frame a task sets how much thinking it needs. Effort is a prompt-and-inference decision, which is why it sits in D4.
- ✓Long multi-step loops are where extra reasoning depth earns its cost. A one-shot reply rarely needs it.
Quick answer
A thinking-budget policy is a rule for how much reasoning each task gets. Fast and shallow for simple work; deep and slow for accuracy-critical work. Once reasoning effort is configurable, one default setting either wastes money on easy tasks or under-thinks the hard ones. For CCA-F D4, the skill is matching reasoning depth to task difficulty, not maximizing it everywhere.
What changed
For a while the only knob was which model you picked. Now reasoning effort is configurable too: the model can run a fast, shallow pass or spend a larger, slower thinking budget before it answers (first-hand: Claude exposes configurable reasoning effort, including an extended-thinking mode for harder tasks).
That turns "pick a model" into "pick a model and a thinking budget." And the moment effort is a dial, leaving it on one setting becomes a decision with a cost:
- Default too low and hard, multi-step tasks get confident, shallow answers.
- Default too high and trivial tasks pay flagship-level time and tokens for nothing.
The fix is not a better default. It is a policy: decide, per class of task, how much reasoning is worth it.
Maxed reasoning everywhere vs. a thinking-budget policy
| Dimension | One effort level for everything | Thinking-budget policy |
|---|---|---|
| Cost | Deep-reasoning price on trivial work | Low budget for easy work, deep only where it counts |
| Latency | Slow on tasks that should be instant | Fast where speed matters |
| Accuracy on hard tasks | Fine, but you cannot tell what needed it | Depth concentrated on the accuracy-critical step |
| Stakes visibility | Uniform: every task looks equally important | Effort tracks where one error is expensive |
| Strategy | "Always think harder" | Smallest budget that meets the bar |
How a thinking-budget policy actually works
A policy is two decisions, made per class of task.
- Budget (how much to think). Match the task's accuracy bar to the smallest reasoning budget that clears it. Do not reach for the deepest mode by default.
- Escalation (when to think harder). Let the low budget handle the common case and raise the budget only for the hard or high-stakes items.
Worked example - "ship a feature with an AI coding agent."
- Scaffolding and boilerplate on a low budget: file moves, imports, routine CRUD do not need deep reasoning.
- The hard core on a deep budget: the concurrency logic, the migration, the security-sensitive path get extended thinking.
- Review and tests back on a low budget: running and formatting is mechanical once the design is settled.
- Spend depth where a mistake is expensive, not uniformly across the whole job.
That is a thinking-budget policy: cheap thinking by default, deep thinking on the step that can break.
A name for it: the Thinking-Budget Policy
The Thinking-Budget Policy - a written rule that maps task classes to reasoning depth, so simple work runs fast and cheap while accuracy-critical work gets the deep budget. You set it once, evaluate it, and revise it; you do not re-decide effort ad hoc on every prompt, and you do not leave one default running everywhere.
Why it matters for CCA-F
This sits in D4 - Prompt Engineering and Structured Output, which is 20% of the exam, and it leans on D1 - Agentic Architecture and Orchestration for the multi-step case.
The proprietary read: D4 questions reward right-sizing reasoning under cost and latency limits, the same discipline as model-tier routing, applied to the effort knob instead of the model.
- Old instinct: if it is wrong, think harder everywhere.
- D4 instinct: think harder on the step that is wrong, and keep the rest cheap.
The distractor pattern to memorize. On D4 scenarios about a slow or expensive workflow, the trap answer is "switch to the deepest reasoning mode for the whole task." The architecturally correct move is one of:
- Match budget to task class (low for routine, deep for accuracy-critical), or
- Escalate effort selectively (cheap pass first, deep budget only on the hard step), or
- Reserve deep reasoning for the failure-prone step and evaluate that the cheaper budget holds elsewhere.
How to apply it
- Write the policy down. List your task classes and the default budget each gets.
- Start cheap. Begin every task at the smallest budget that could plausibly meet the bar.
- Escalate on stakes, not on vibes. Raise the budget for steps where one error is expensive.
- Separate the knobs. Decide model tier and thinking budget independently; pair them per task.
- Evaluate downgrades. Prove a lower budget meets the bar on the real task before adopting it.
- Review the bill. If every task runs deep, that uniform cost is the signal your policy is missing.
The meta-skill, and the D4 exam skill, is the same: accuracy per dollar comes from spending reasoning where it changes the answer, not from thinking harder everywhere.
5 direct routes into the scored material.
- conceptsPlan mode is the clearest place reasoning effort pays for itself: think before acting on hard work, skip it on trivial edits.
- conceptsHow you frame a task sets how much thinking it needs. Effort is a prompt-and-inference decision, which is why it sits in D4.
- conceptsLong multi-step loops are where extra reasoning depth earns its cost. A one-shot reply rarely needs it.
- conceptsYou only know a cheaper thinking budget is good enough by measuring it on the real task. A budget without eval is a guess.
- exam-guideD4 (Prompt Engineering and Structured Output) is 20% of the exam and rewards matching reasoning depth to the task, not maxing it everywhere.
Share this post.
One share is one less person stuck on the same question.