
What this system is, and its 4 parts
Not every request deserves the most expensive model. A one-line classification and a multi-step agentic refactor have wildly different intelligence requirements, and routing both through the same top-tier model is the single most common way teams overspend on Claude. This scenario is the router that sits in front of your requests: a cheap first pass decides how hard the task actually is, then the request is sent to the cheapest model tier that can do it well, with an explicit, data-driven escalation path rather than a blanket 'always use the best model' default.
Router
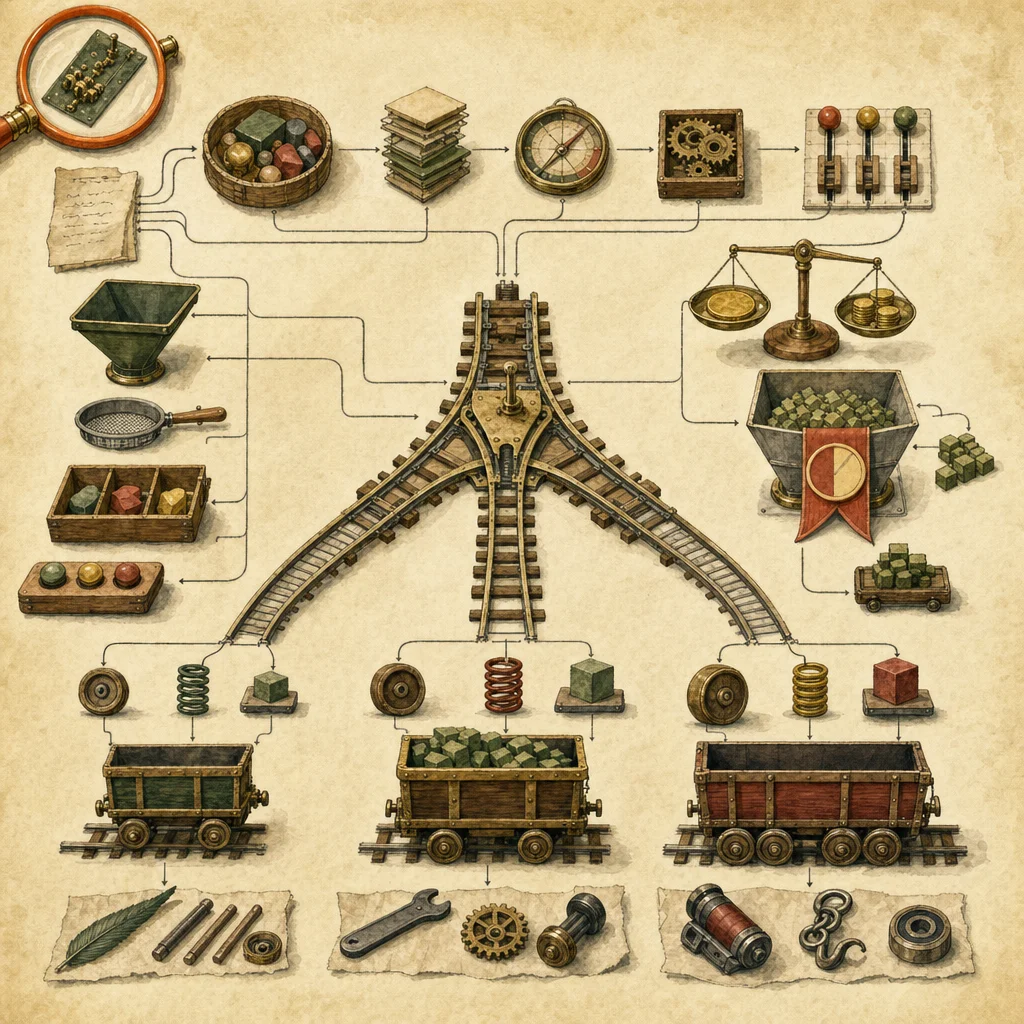
Haiku 4.5 classification passA single cheap Haiku 4.5 call (or a lightweight heuristic) classifies request complexity/intent before the real request is dispatched to the right tier.
Configurationrouter_resp = client.messages.create(model="claude-haiku-4-5", max_tokens=16, output_config={"effort":"low"}, ...). Output is a tier label, not the final answer.Concept: model-selection-tradeoffs →Workhorse Tier
Sonnet 5 - defaultThe default destination for the large majority of production requests: near-Opus quality on coding/agentic work at a fraction of the cost.
Configurationmodel="claude-sonnet-5", output_config={"effort":"high"} (the default; tune down for routine work).Concept: model-selection-tradeoffs →Escalation Tier
Opus 4.8 - explicit criteriaReserved for requests that meet a documented bar: long-horizon agentic work, high-stakes correctness requirements, or tasks that measurably fail on Sonnet 5 in the eval harness.
Configurationmodel="claude-opus-4-8", output_config={"effort":"high"} or "xhigh" for the hardest coding/agentic subset.Concept: model-selection-tradeoffs →Fallback Handler
graceful tier step-downOn a 429/529 from the escalation tier, retries the request one tier down rather than failing outright.
Configurationexcept RateLimitError: retry with model=WORKHORSE_MODEL instead of the escalation tier.Concept: accuracy-latency-cost-tradeoffs →
The problem
- Simple, high-volume requests answered cheaply and fast.
- Hard, high-stakes requests get the intelligence they actually need.
- A graceful fallback when the highest tier is rate-limited, instead of a hard failure.
- Routing every request to Opus 4.8 'to be safe' multiplies cost 5x with no measurable quality gain on the 80% of traffic that's routine.
- Routing every request to Haiku for cost savings degrades quality on genuinely complex requests that need more reasoning depth.
- No fallback tier on a 429/529 from the top model fails the whole request instead of degrading gracefully.
- ✓ Routing decision made in < 200ms via a cheap classification pass
- ✓ Escalation criteria documented and measured, not guessed
- ✓ Blended per-request cost tracked and trending down as routing improves
- ✓ Rate-limit on any one tier degrades to the next tier, never a hard failure
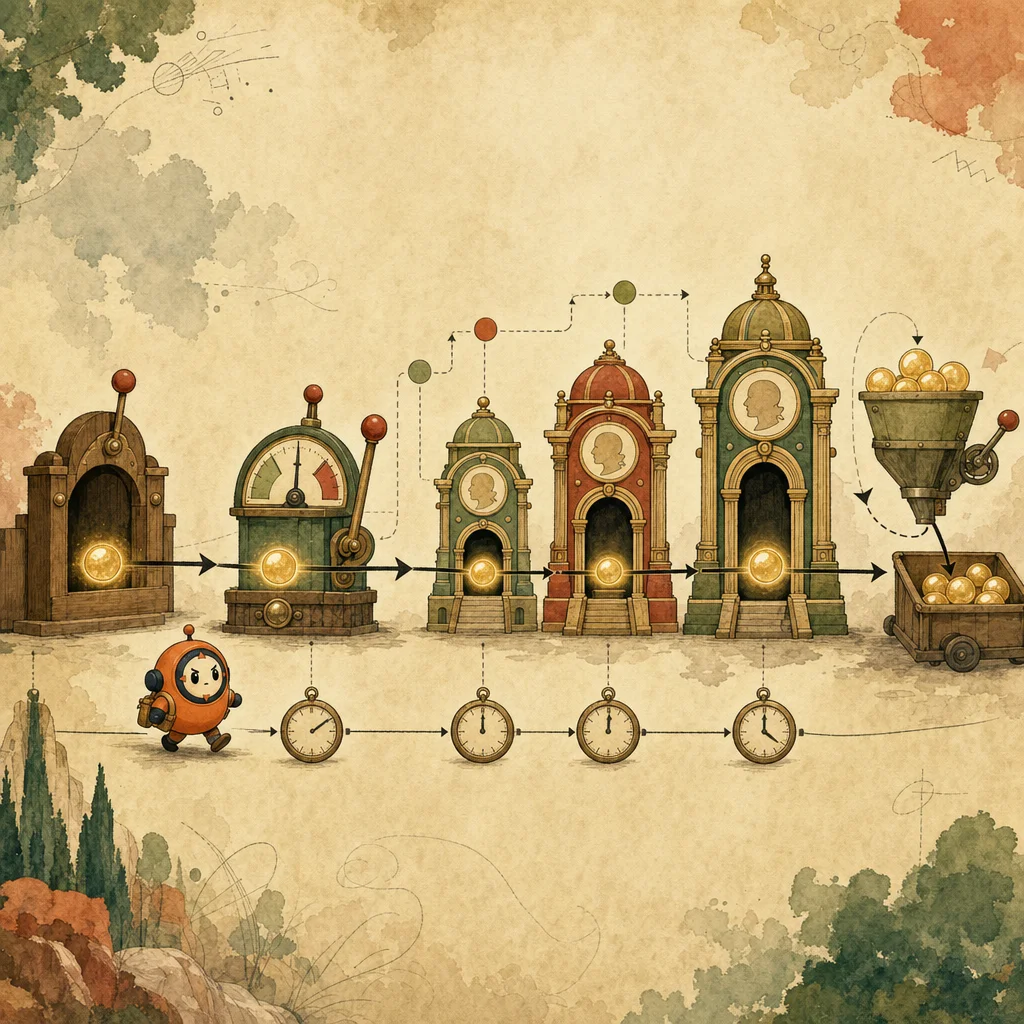
One run, traced end to end
6 steps to production
Classify the request with a cheap Haiku pass
The router call itself must be cheap. Keep max_tokens tiny, effort low, and ask only for a tier label, not an explanation.
Concept: model-selection-tradeoffs →def classify_tier(request_text: str) -> str:
resp = client.messages.create(
model="claude-haiku-4-5",
max_tokens=16,
output_config={"effort": "low"},
system="Classify the request as one of: simple, standard, complex. Reply with one word.",
messages=[{"role": "user", "content": request_text}],
)
return resp.content[0].text.strip().lower()Route to a tier and set per-tier effort
Map the classification to a model + effort pair. Sonnet 5 is the default for 'standard'; escalate only 'complex' to Opus.
Concept: accuracy-latency-cost-tradeoffs →Dispatch on the chosen tier
The router's decision feeds a normal Messages API call - the routing logic and the actual request are two separate calls, not one combined prompt.
Concept: model-selection-tradeoffs →Fall back a tier on rate limit or overload
Catch typed rate-limit/overload exceptions on the escalation tier and step down one tier rather than surfacing a hard failure to the user.
Concept: accuracy-latency-cost-tradeoffs →Move non-interactive bulk work to the Batches API
Anything latency-insensitive (nightly re-scoring, bulk classification) should run through Message Batches for the 50% discount rather than live requests.
Concept: model-selection-tradeoffs →Log routing decisions for a data-driven escalation policy
Every dispatched request logs the chosen tier, tokens, cost, and a downstream quality signal, so escalation criteria come from measured data, not intuition.
Concept: accuracy-latency-cost-tradeoffs →8 decisions the exam turns into distractors
claude-opus-4-8 for every request
claude-sonnet-5
the same model as the actual request, run twice
claude-haiku-4-5, tiny max_tokens, low effort
gut feeling that a task 'seems hard'
measured failure patterns on the workhorse tier, tracked over time
surface a hard failure to the user
step down to the workhorse tier and retry
Every request, regardless of complexity, is sent to claude-opus-4-8 'to be safe'.
Route routine traffic through Sonnet 5 by default; reserve Opus for a documented, measured escalation criterion.
A 429 from the escalation tier propagates as a user-facing error.
Catch the typed rate-limit exception and retry one tier down before failing.
Code sets temperature=0 on Opus 4.8 expecting identical outputs every run.
Sampling parameters are removed on Opus 4.7+ and Sonnet 5 (400 error). Even where they existed, temperature=0 never guaranteed identical outputs - use prompting for consistency instead.
Cost model assumes Sonnet 5 token counts match Sonnet 4.6 for the same text.
Sonnet 5 uses a new tokenizer producing roughly 30% more tokens for the same input than Sonnet 4.6 - re-baseline with count_tokens rather than reusing an old multiplier.
Cost & latency
Router classification pass and any simple, high-volume traffic.
Default workhorse tier for the bulk of production requests.
Escalation tier only, gated by measured criteria, not the default path.
80% Haiku+Sonnet routine traffic, 15% Sonnet standard, 5% Opus escalation - illustrative, tune against your own traffic mix.
Check every gate before release
3 exam-pattern questions
Work through one question at a time, check the architecture, then move through the set.
A team routes every production request through Opus 4.8 because 'it's the smartest model'. Cost is 5x a comparable Sonnet-5-default setup with no measurable quality difference on 80% of traffic. What's the fix?
Frequently asked
Isn't running a Haiku classification call before every request just adding cost and latency?
The router call is deliberately tiny (max_tokens ~16, effort low), so it's a small fraction of a cent and tens of milliseconds. The savings from routing 80% of traffic away from Opus far outweigh that overhead.
How do I decide the actual escalation criteria, not just 'when it feels hard'?
Feed the eval harness (Scenario CCD-F.5) results: track which request patterns fail or score poorly on the workhorse tier, and route exactly those patterns to the escalation tier. This turns the router into a measured policy instead of a guess.
Should effort tuning happen before or after considering a bigger model?
Before. Tuning output_config.effort on the current tier is cheaper than jumping a model tier, and often closes the gap - reserve the tier jump for cases where effort tuning alone doesn't get there.
Does prompt caching change the router's economics?
Yes - if the same system prompt and tools are shared across all three tiers, caching that shared prefix reduces the cost delta between tiers even further, since the fixed overhead per request drops regardless of which model serves it.