
What this system is, and its 4 parts
This is the app most developers build first: a chat UI backed by Claude, with responses that stream in word by word instead of appearing all at once after a long wait. It exists because a 6-second pause before any text appears feels broken to a user, while the same 6 seconds spent watching words stream in feels fast. The hard part isn't calling the API, it's everything around the call: keeping the conversation history somewhere durable, knowing when the context window is about to overflow, and making sure a client disconnect mid-stream doesn't silently lose the assistant's answer.
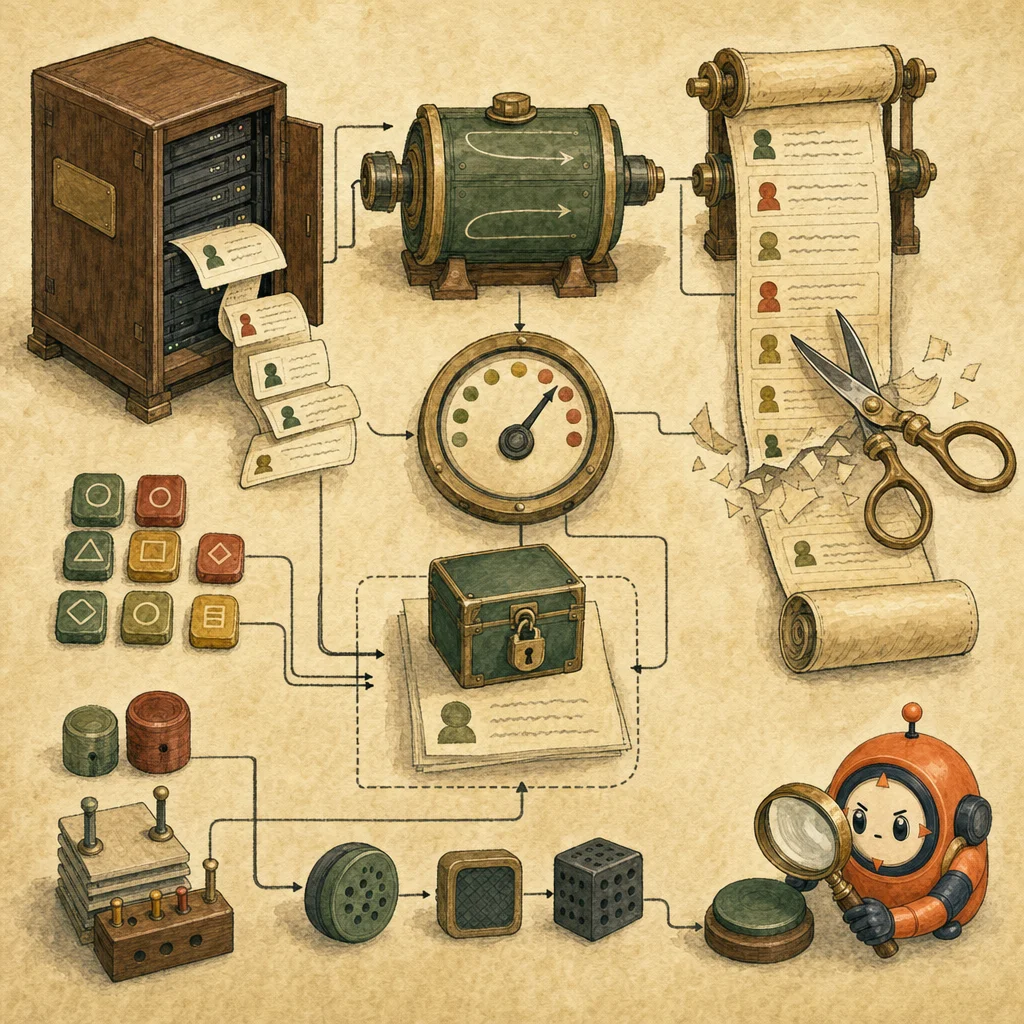
Stream Handler
SSE consumer - UI rendererOpens client.messages.stream(), listens for text deltas, and writes them to the client connection as they arrive instead of buffering the whole response.
Configurationclient.messages.stream({model, max_tokens, system, messages}) with a text-delta listener; call .finalMessage() once to get the complete Message for persistence.Concept: streaming →Session Store
server-owned historyPersists the full message array per session_id in a database. The API is stateless - every request resends the whole history, so this store is the only source of truth.
Configurationsessions[session_id].messages.push({role: 'assistant', content: response.content}) - the full content array, never just the extracted text.Concept: session-state →Context Budget Manager
count_tokens + compactionCalls messages.count_tokens() before each turn against the live model. When the count nears the working budget, trims oldest turns or engages compaction rather than sending an oversized request.
Configurationif count_tokens(messages).input_tokens > BUDGET: trim oldest non-system turns, or (beta) enable context_management compaction with beta compact-2026-01-12.Concept: context-window →
Cache Breakpoint
system prompt - ephemeralMarks the last block of the (stable, non-interpolated) system prompt with cache_control so repeated turns in the same conversation read from cache instead of reprocessing the full prefix.
Configurationsystem: [{type: "text", text: SYSTEM_PROMPT, cache_control: {type: "ephemeral"}}] - SYSTEM_PROMPT never has a timestamp or session id interpolated into it.Concept: prompt-caching →The problem
- See the response start appearing within ~200ms, not after the full generation finishes.
- Never lose an in-progress answer when the browser tab closes or the network blips.
- Keep a 40-turn conversation coherent without the context window silently overflowing.
- Client-side-only history means refreshing the page loses the whole conversation (the Messages API is stateless - nothing is stored server-side unless you store it).
- Appending only response.text back onto history drops tool_use and thinking blocks, corrupting the next turn's context.
- An unbounded messages array eventually exceeds the context window and every request starts failing at once instead of degrading gracefully.
- ✓ Time-to-first-token < 300ms on a warm cache
- ✓ Zero conversations lost on client disconnect (server-side persistence, not client memory)
- ✓ Context budget enforced before the 1M-token ceiling, with graceful compaction
- ✓ Full response.content persisted per turn, including non-text blocks
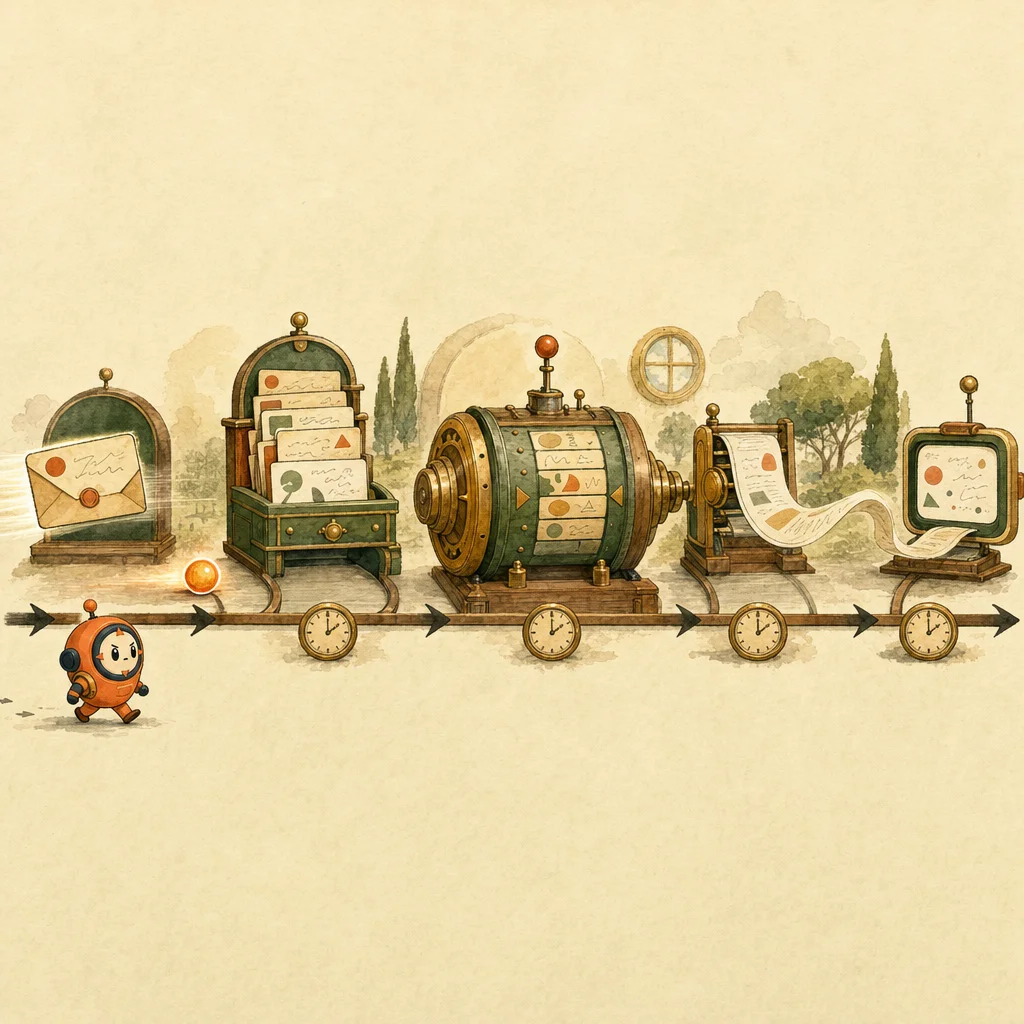
One run, traced end to end
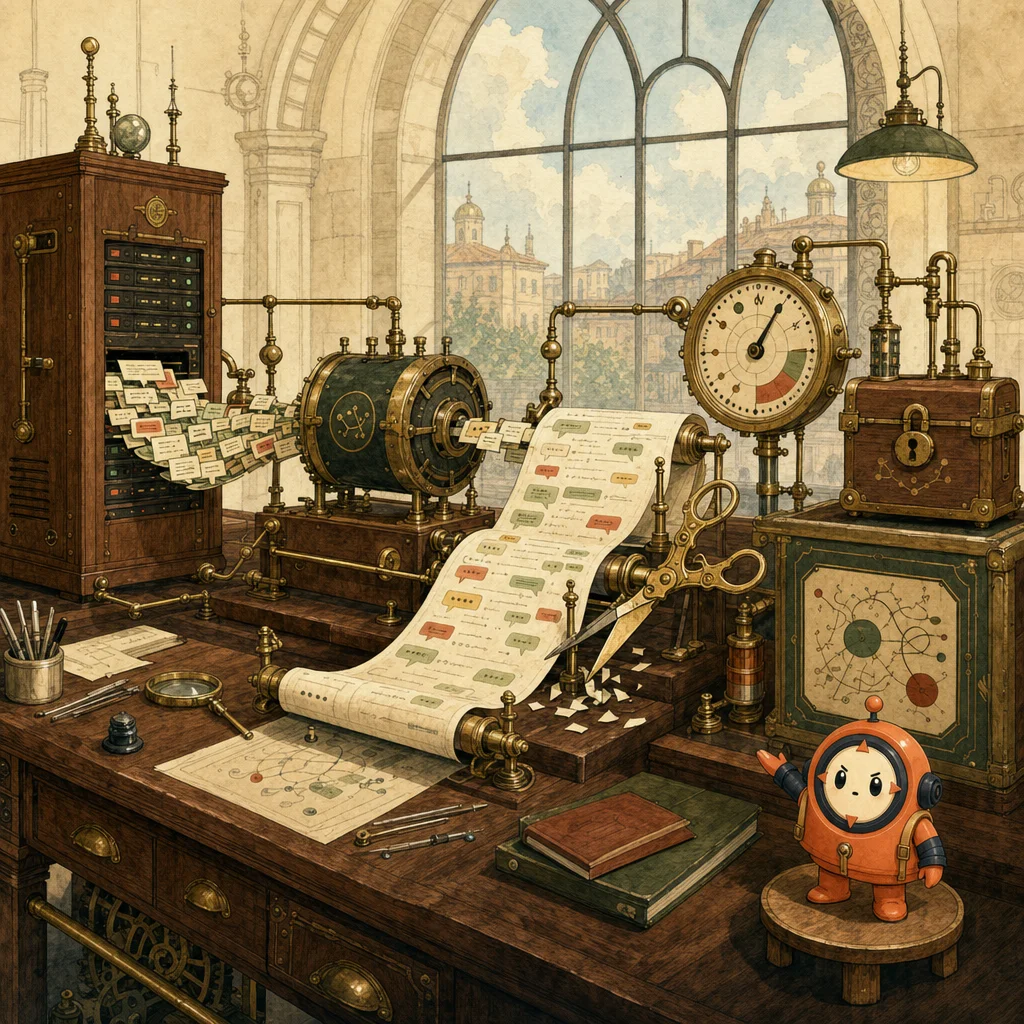
6 steps to production
Open a stream and render deltas
Use the SDK's stream() helper rather than a manual SSE parser. Only text_delta events touch the UI; other event types drive server-side bookkeeping.
Concept: streaming →client = Anthropic()
def stream_turn(messages, system_prompt):
with client.messages.stream(
model="claude-sonnet-5",
max_tokens=4096,
system=[{"type": "text", "text": system_prompt,
"cache_control": {"type": "ephemeral"}}],
messages=messages,
) as stream:
for text in stream.text_stream:
yield text # forward to the client connection
return stream.get_final_message()Persist the full content array, not the text
The final assistant turn must carry every content block, including thinking or tool_use blocks, or the next request loses structure the API needs to stay coherent.
Concept: session-state →Budget the context window before every turn
Call count_tokens against the model you're about to use (token counts are model-specific) and trim or compact before the request, not after it fails.
Concept: context-window →Branch on stop_reason after the stream ends
The stream's final message carries the same stop_reason contract as a non-streaming call. Handle max_tokens and refusal explicitly instead of assuming every stream ends cleanly.
Concept: streaming →Inject runtime context without breaking the cache
On models that support it, append a role: 'system' message to the array for mid-conversation operator context instead of rewriting the top-level system prompt, which would invalidate the cached prefix on every turn.
Concept: prompt-caching →Handle client disconnect without losing the turn
The Messages API stream itself has no server-side replay. Keep the request running server-side even if the client connection drops, and persist on completion regardless of whether anyone was still listening.
Concept: session-state →8 decisions the exam turns into distractors
client-side only (localStorage/component state)
server-side session store, keyed by session_id
just the extracted text string
the full response.content array
let the request fail, then handle the error
count_tokens before the request, trim/compact proactively
claude-opus-4-8 for every message
claude-sonnet-5
Server stores finalMessage.content[0].text as the assistant turn.
Store the full content array. Non-text blocks are silently dropped otherwise, breaking later turns.
System prompt string includes f"Current time: {now()}" at the top.
Keep the system prompt byte-identical across requests. Inject dynamic context via a role: 'system' message instead.
Messages array grows unbounded until a request 400s on context length.
Call count_tokens before every request and trim or compact before it fails, not after.
Assistant text is only ever rendered to the open connection, never saved.
Always call .finalMessage() / get_final_message() and persist it, independent of whether the client is still connected.
Cost & latency
System prompt + tool defs read from cache after turn 1; only new user text + growing tail cost full price.
At $2/$10 intro per MTok with ~70% cache-read rate on the stable prefix.
Streaming avoids waiting for the full generation; first token arrives as soon as the model emits it.
Check every gate before release
4 exam-pattern questions
Work through one question at a time, check the architecture, then move through the set.
Your chat app persists response.content[0].text as the assistant turn. After adding a tool, multi-turn conversations start behaving inconsistently. Why?
Frequently asked
Do I need a database, or can I keep history in memory?
Use a database (or Redis with persistence) for anything beyond a local demo. In-memory history is lost on process restart and doesn't scale past one server instance.
Should I stream on every request?
Stream whenever max_tokens is large or the user is waiting live for the response - which is essentially always true for a chat UI. Non-streaming is fine for short, backend-only calls with small max_tokens.
How do I know when to trim history versus use compaction?
Trimming (dropping oldest turns) is simple and works for most chat apps. The beta compaction feature (compact-2026-01-12) is worth adopting when you need the model to retain awareness of dropped history rather than losing it outright - useful for long support or coaching sessions.
What model should a general-purpose chat app default to?
Claude Sonnet 5 for the vast majority of conversational traffic. It is the best cost/quality balance in the current lineup; reserve Opus 4.8 for a router-driven escalation path (see the model-selection scenario), not as the default.
Is it safe to cache the entire conversation, not just the system prompt?
The message array is not typically cached because it grows every turn and each growth invalidates a naive full-array cache marker. Cache the stable prefix (system + tool defs); let the growing message tail be uncached, or use auto top-level caching which places the marker on the last cacheable block.