
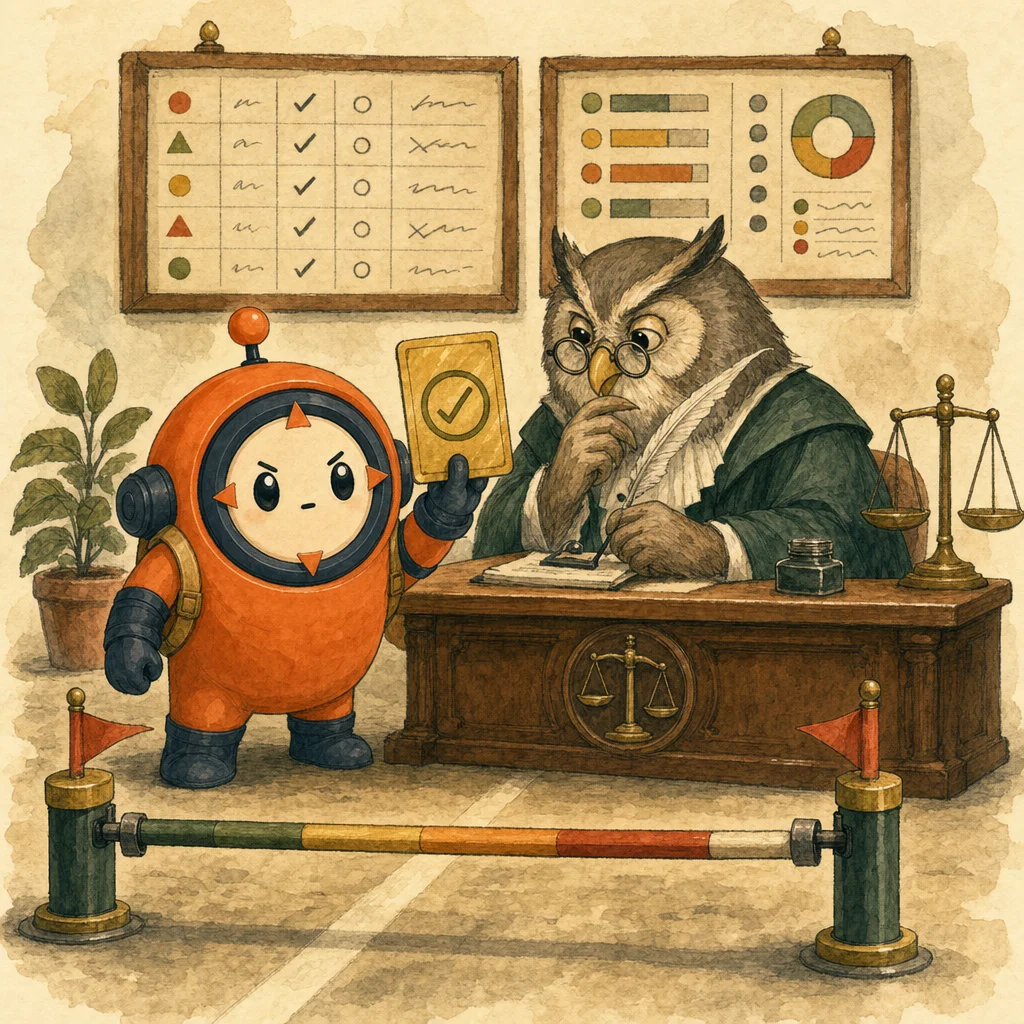
What this system is, and its 4 parts
Once an agent is in production, 'it seemed fine when I tried it' stops being a testing strategy. This scenario is the harness that replaces manual spot-checking: a versioned set of representative inputs with known-good expected behavior, run in bulk, graded automatically, and compared against a baseline before any prompt or model change ships. It exists because the two most common ways teams get burned are shipping a prompt tweak that silently breaks an edge case, and grading agents only on how the final text reads while ignoring whether they actually called the right tools in the right order.
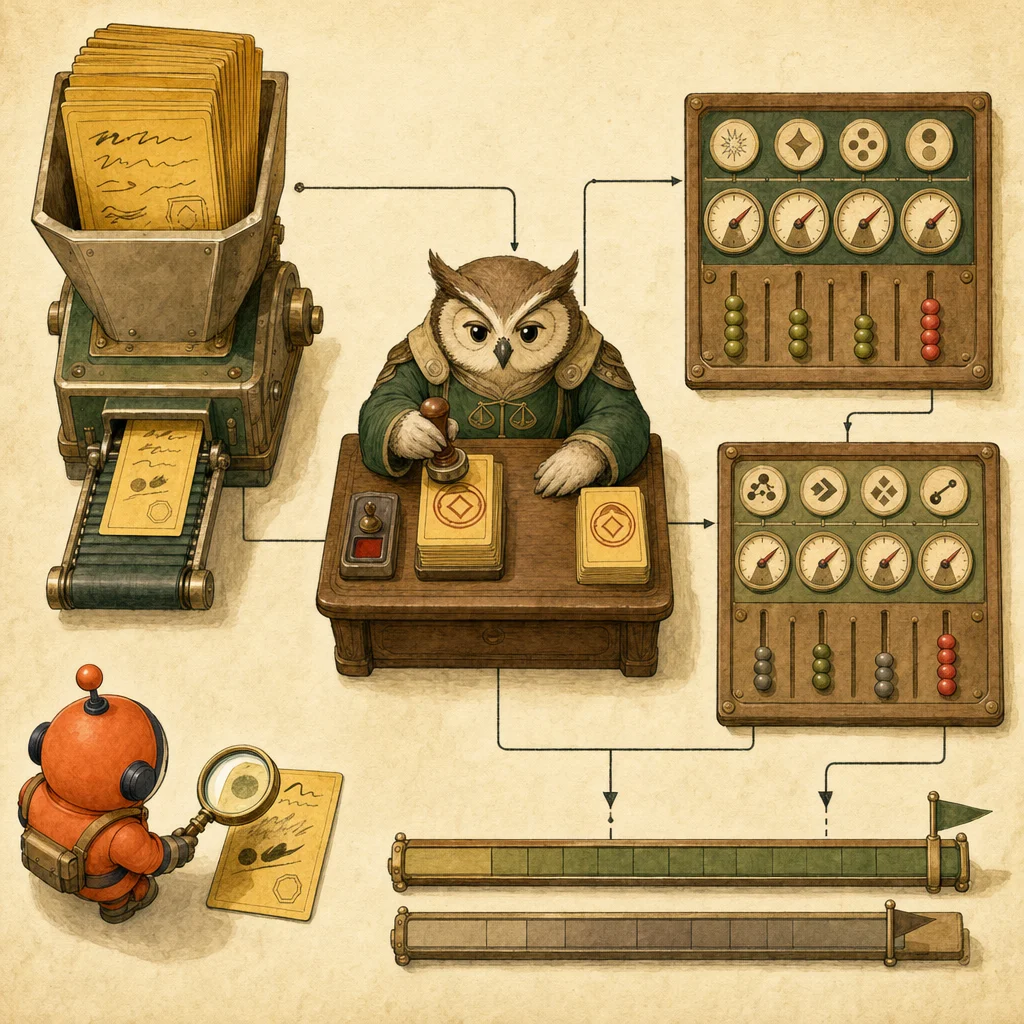
Golden Set
versioned inputs + expected behaviorA repo-tracked set of representative test cases, each with an input and the expected stop_reason/tool sequence/output shape, versioned alongside the prompt it was built against.
Configurationgolden_set_v3.jsonl - one JSON object per line: {id, input, expected_tools, expected_shape}.Concept: evaluation →Batch Runner
Message Batches APISubmits the full golden set as a single batch job rather than sequential live requests, at half the per-token cost and without holding a connection open per case.
Configurationclient.messages.batches.create(requests=[{custom_id, params} for each golden-set case]).Concept: batch-api →LLM Judge
structured, deterministic scoringA model at least as capable as the system under test, forced into a fixed JSON schema via output_config.format so scores are parseable and comparable across runs.
Configurationoutput_config={"format": {"type": "json_schema", "schema": JUDGE_SCHEMA}} - never a prefill (400s on current models).Concept: structured-outputs →Regression Gate
baseline comparisonCompares the new run's pass rate against the versioned baseline and blocks deployment if it regresses, turning eval results into a CI-style check rather than a one-off report.
Configurationif new_pass_rate < baseline_pass_rate - TOLERANCE: fail the deploy step.Concept: evaluation →
The problem
- Know before shipping whether a prompt or model change made things better or worse.
- Grade what the agent actually did (tool calls, sequence), not just how the final text reads.
- Run evaluations cheaply at scale, not one request at a time against a live endpoint.
- Grading only the final text lets an agent that skipped identity verification still score well because the refund text 'looked right'.
- Using a weaker or cheaper model as the judge than the system under test produces unreliable, inconsistent scores.
- Re-running evals ad hoc with no versioned golden set gives you no regression signal, every run is a fresh, incomparable snapshot.
- ✓ Golden set versioned alongside the prompt/model it was built against
- ✓ Tool-call correctness scored separately from output-text quality
- ✓ Judge forced into structured, parseable output via output_config.format
- ✓ New versions gated on matching or beating the baseline pass rate before deploy
One run, traced end to end
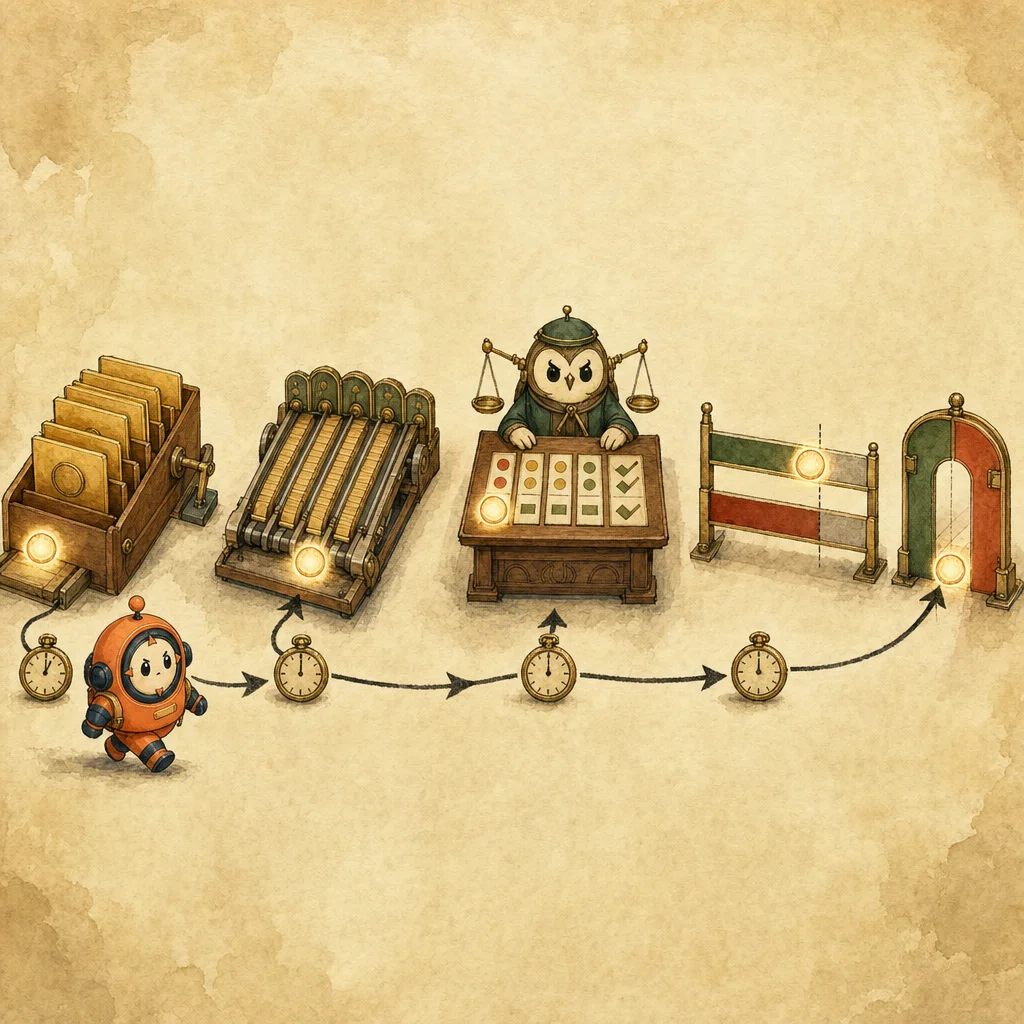
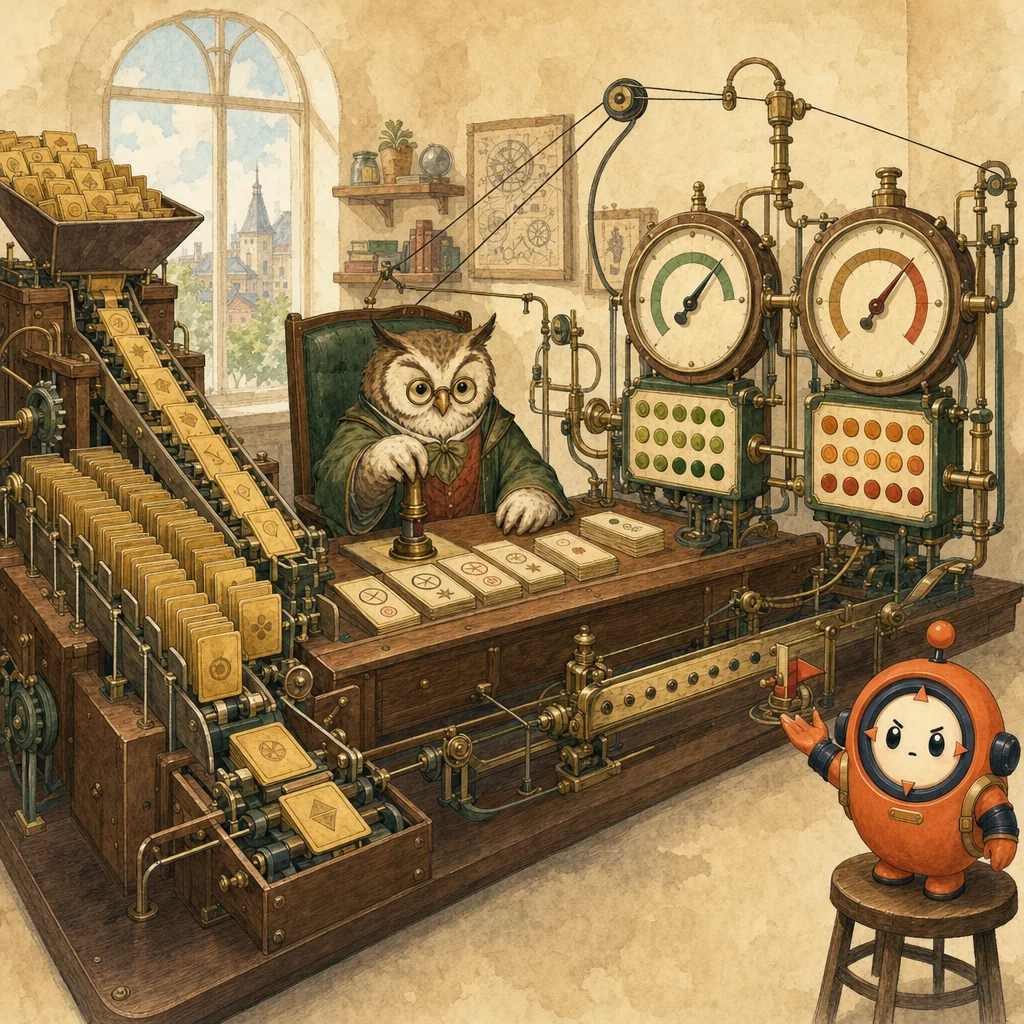
6 steps to production
Build a versioned golden set
Each case pairs an input with the expected tool sequence and output shape. Version it in the repo alongside the prompt it was authored against.
Concept: evaluation →golden_set = [
{
"id": "refund-happy-path",
"input": "I want a refund for order 42, it arrived damaged.",
"expected_tools": ["verify_customer", "lookup_order", "process_refund"],
"expected_stop_reason": "end_turn",
},
{
"id": "refund-over-cap",
"input": "I need a $900 refund on order 55.",
"expected_tools": ["verify_customer", "lookup_order", "escalate_to_human"],
"expected_stop_reason": "end_turn",
},
]Run the golden set through Message Batches
Submit every case as one batch job instead of sequential live requests - half the cost, and it doesn't hold connections open per case.
Concept: batch-api →Score tool-call correctness separately from text quality
Extract the actual tool call sequence from the response and compare it to the expected sequence directly - exact-match grading, not judge opinion, for structured behavior.
Concept: evaluation →Grade open-ended output with a structured LLM judge
Force the judge into a JSON schema so scores are parseable and comparable. Use a model at least as capable as the system under test, and never a prefill.
Concept: structured-outputs →Gate deploys on the versioned baseline
Compare the new run's pass rate to the checked-in baseline. A regression beyond tolerance blocks the deploy, the same way a failing unit test would.
Concept: evaluation →Replay failures from full content blocks, not just final text
When a case fails, inspect the entire content array (tool_use, tool_result, stop_reason per turn) to see exactly where the agent diverged, not just the final answer.
Concept: debugging-llm-system-failures →8 decisions the exam turns into distractors
LLM judge opinion on whether it 'seems right'
exact-match against the expected sequence
exact string match against a reference answer
LLM judge, forced into structured output
the cheapest available model, to save eval cost
at least as capable as the system under test
sequential live requests in a loop
Message Batches API
The judge scores only the final response text, missing that the agent skipped verify_customer.
Score tool-call sequence separately (exact-match) from output-text quality (LLM judge).
Haiku 4.5 is used to judge output from a Sonnet-5-powered agent, producing noisy scores.
Use a judge model at least as capable as the system under test.
The eval script's test cases live only in someone's scratch notebook, changing between runs.
Version the golden set in the repo alongside the prompt/model it was built against.
Judge prompt ends with an assistant-turn prefill like '{"correct": ' to force JSON shape.
Assistant-turn prefills return a 400 on current models. Use output_config.format (structured outputs) instead.
Cost & latency
50% Batches discount on Sonnet 5 traffic for 100 short-to-medium cases with tool use.
A separate Opus 4.8 (or Sonnet 5) call per case for open-ended text grading; skip it for pure tool-sequence cases.
Check every gate before release
3 exam-pattern questions
Work through one question at a time, check the architecture, then move through the set.
Your eval harness scores an agent 95% pass rate, but production shows it frequently skips identity verification before processing refunds. What's the gap?
Frequently asked
How big should a golden set be?
Start with 20-50 cases covering the main happy paths and known edge cases (policy boundaries, ambiguous intent, tool failures). Grow it every time production surfaces a new failure mode - each incident becomes a new golden-set case so it can never regress silently again.
Should every case use an LLM judge?
No. Use exact-match grading for anything with a ground truth (tool sequence, structured output fields, stop_reason). Reserve the LLM judge for genuinely open-ended text quality, where there's no single correct string.
How often should the harness run?
On every prompt or model change before it ships, as a CI-style gate, plus on a schedule (e.g. nightly) against production traffic samples to catch silent drift that wasn't triggered by a code change.
What tolerance should the regression gate use?
Start conservative (e.g. 2 percentage points) and tune based on how noisy your judge scoring is. A tolerance of 0% will flag noise as regressions; too loose a tolerance lets real regressions through.