
What this system is, and its 5 parts
Everyone who uses Claude regularly eventually gets an output that's just... off. Too generic, missing the point, confidently wrong, or technically responsive but useless for what you actually needed. The instinct is usually to regenerate and hope, or worse, to quietly rewrite the whole thing by hand and never figure out why it went wrong. This scenario is about diagnosing a weak output like a professional would diagnose a weak first draft from a junior colleague: systematically, by asking what was actually missing, not by guessing. No code, no settings menus, just the same handful of questions asked in the same order, every time.
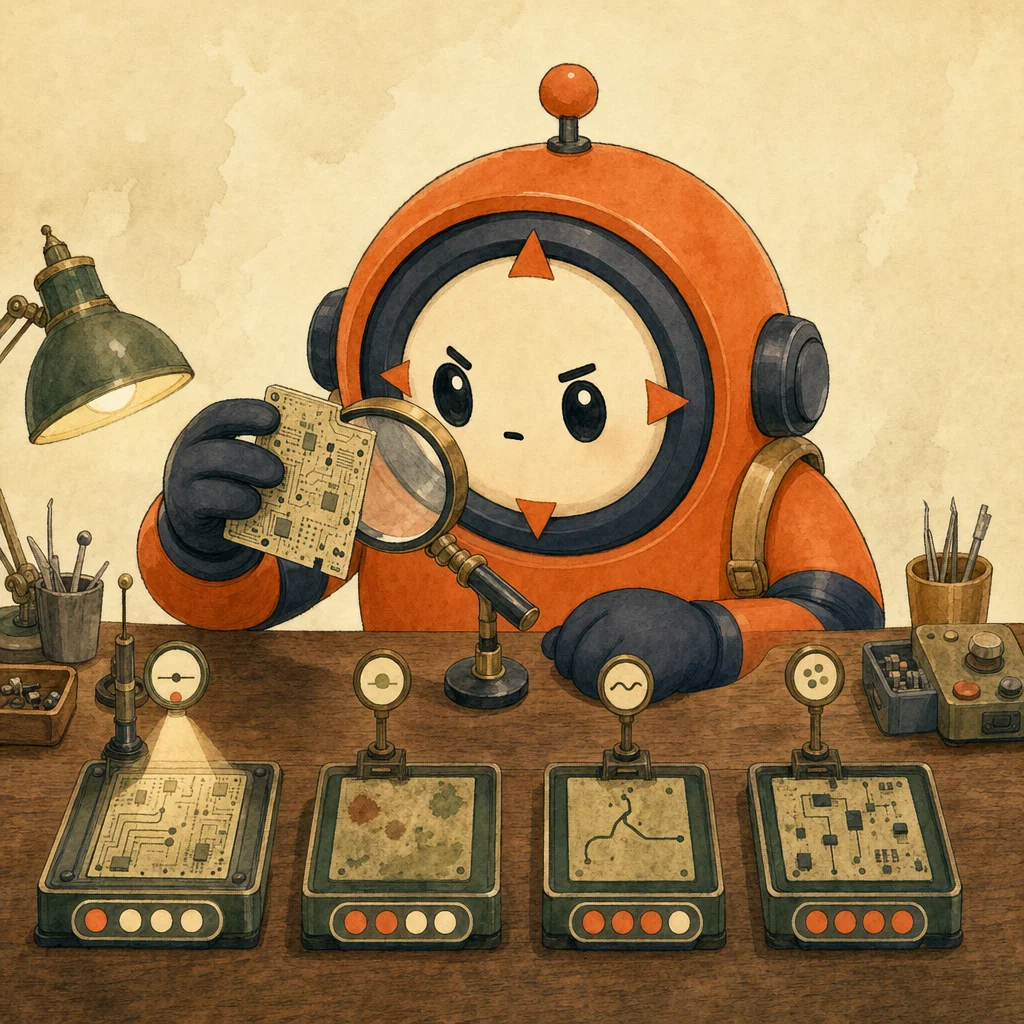
Weak-Output Diagnosis
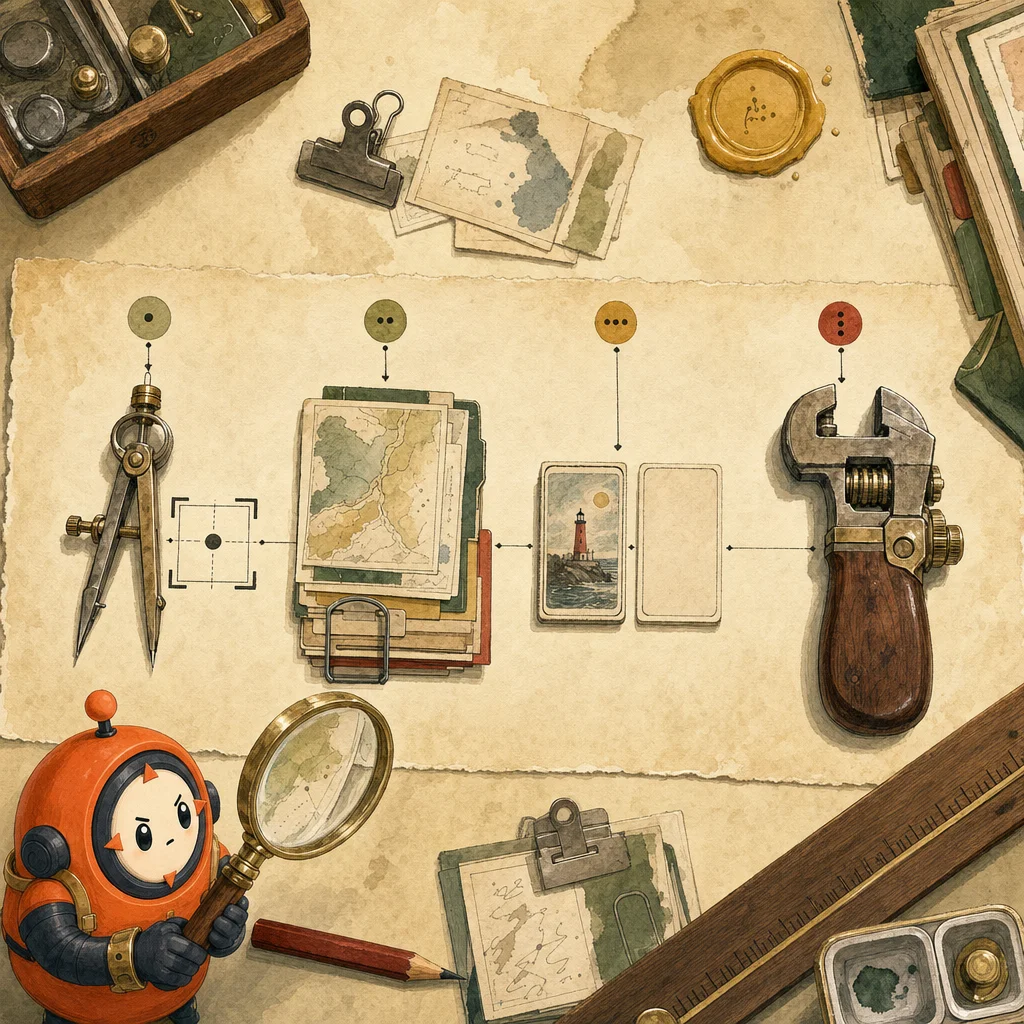
name the specific problem firstBefore touching the prompt again, name precisely what's wrong: too generic, missing a specific requirement, wrong tone for the audience, factually off, or structurally not what was asked for. "It wasn't great" isn't a diagnosis, it's a shrug.
ConfigurationOne sentence: "This is too generic because it doesn't reference our client's specific situation" is a diagnosis. "This isn't good" is not.Concept: adjusting-approach-from-feedback →
Prompt Specificity Check
the first thing to check, almost alwaysMost weak outputs trace back to a vague or underspecified prompt: no stated audience, no stated format, no stated constraints. Before considering anything else, check whether the original ask actually told Claude what a good answer would look like.
ConfigurationDid the prompt state who this is for, what format it should take, and what "good" looks like? If any of these were left implicit, that's very likely the actual problem.Concept: task-type-prompting-strategies →
Context Completeness Check
did Claude actually have what it neededIf the prompt was reasonably specific, check next whether Claude had the actual source material it needed, the client background, the prior decisions, the relevant data, or whether it was working from a vague description of those things instead.
ConfigurationWas the actual source document attached, or was it described from memory in the prompt? Missing or paraphrased context is the second most common cause of a weak output, right behind prompt vagueness.Concept: adjusting-approach-from-feedback →
Example Anchor Check
would a sample of "good" have helpedFor tasks where tone, format, or style matters and is hard to describe in words, check whether providing one concrete example of a similarly good output would have anchored Claude more effectively than more description would.
ConfigurationIf the task is genuinely about matching a specific voice or format (a particular report style, a particular tone), one short example usually outperforms another paragraph of description.Concept: task-type-prompting-strategies →
Model-Tier Escalation Check
the last thing to check, not the firstOnly after prompt specificity, context completeness, and example-anchoring have been ruled out as the cause, consider whether the task genuinely exceeds the current model tier's reasoning capability and warrants a tier upgrade for this specific task.
ConfigurationAsk: if I fixed the specificity, context, and examples and the output is still weak on genuinely hard reasoning, that's a real signal to escalate tier. If those weren't fixed first, tier escalation is premature.Concept: optimizing-ai-workflows-for-efficiency →
The problem
- A consistent method for fixing a bad output, not a different guess every time.
- To avoid wasting time regenerating the same weak result over and over with no real change.
- To know when the problem is genuinely "this model tier can't do this" versus something fixable in how the task was set up.
- Hitting regenerate repeatedly hoping for a better roll, without changing anything about the prompt or context.
- Assuming a weak output means "the model isn't good enough" and escalating to a higher tier, when the real problem was missing context.
- Quietly rewriting the output by hand every time without ever diagnosing why it came back weak, so the same problem repeats on the next task.
- ✓ The specific reason the output was weak has been identified, not just "it wasn't great"
- ✓ A fix was applied to the actual cause, prompt specificity, missing context, or a missing example, before regenerating
- ✓ Model-tier escalation is used only after prompting and context fixes have been ruled out
- ✓ The diagnosis is fast, a couple of minutes, not a long investigation
One run, traced end to end
6 steps to production
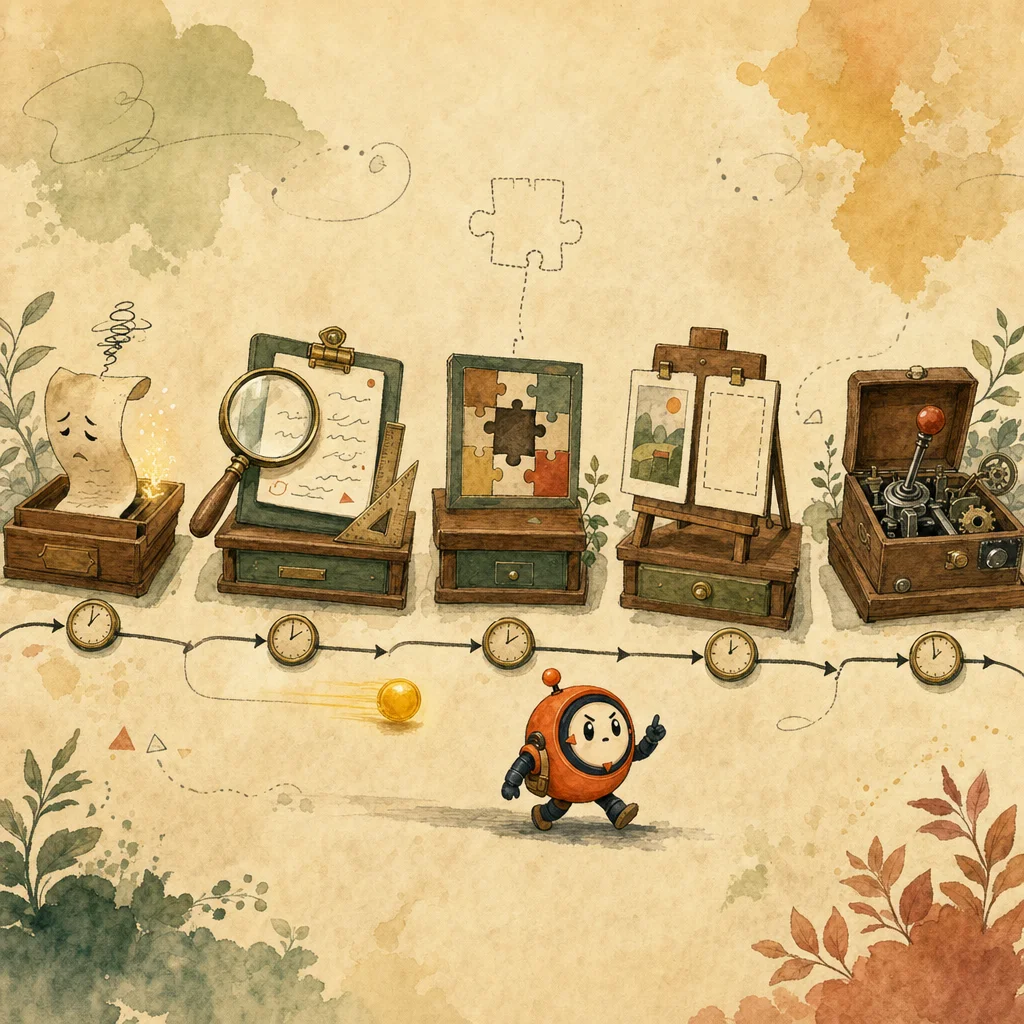
Name the specific problem with the output
Write one sentence describing precisely what's wrong: too generic, missing a stated requirement, wrong tone, factually off, or wrong structure. This single step prevents the common failure of regenerating repeatedly without ever identifying what actually needs to change.
Concept: adjusting-approach-from-feedback →Check prompt specificity first
Look back at the original prompt: did it state the audience, the format, and what a good answer would look like? Most weak outputs trace back to an underspecified prompt, so this is almost always the first thing to check, not the last.
Concept: task-type-prompting-strategies →Check whether Claude had the actual source material
If specificity looks fine, check whether the real source documents were attached, or whether Claude was working from a paraphrased or partial description of them. Missing context produces weak, generic-sounding outputs that look like a capability problem but aren't.
Try one concrete example before assuming it's unfixable
For tone- or format-sensitive tasks, add one short example of a similarly good output and re-ask. This often resolves what looks like a stubborn quality problem faster than additional written description would.
Only then consider a model-tier escalation
If specificity, context, and an example have all been tried and the output is still weak specifically on hard reasoning, that's a genuine signal the task may need a stronger model tier. Escalating tier before trying the first three steps usually just produces a more expensive, still-weak output.
Concept: optimizing-ai-workflows-for-efficiency →Carry the fix forward, not just for this one output
If the diagnosis was missing context or a vague prompt template, fix the underlying prompt or workflow so the next similar task doesn't hit the same problem. A one-time patch on a single output is a partial fix; catching the pattern is the real one.
8 decisions the exam turns into distractors
Hit regenerate repeatedly and hope for a better result
Diagnose the specific cause before changing anything
Assume the model isn't capable enough and escalate tier
Check whether the actual source material was provided
Jump straight to the highest model tier as a first move
Prompt specificity → context → example → model tier, in that order
Write another paragraph trying to describe the style in words
Provide one concrete example of the desired style
A weak output gets regenerated five times in a row with no change to the prompt or context, producing five variations of the same problem.
Diagnose the specific cause first, then change the actual input (prompt, context, or example) before regenerating.
A generic-feeling output gets treated as a capability problem, and the task is immediately rerun on the highest model tier without changing anything else.
Check prompt specificity and context completeness first. Most generic outputs are a missing-context problem, not a capability ceiling.
A team member rewrites a weak output by hand every time without ever figuring out why it came back weak, so the same issue recurs on the next similar task.
Take the extra minute to name the specific cause and fix the underlying prompt or context, so the fix carries forward to future tasks.
A weak, off-tone output gets re-prompted with three more paragraphs of description of the desired tone, with limited improvement.
Provide one concrete example of the desired tone or format instead of adding more descriptive instruction.
Cost & latency
The four-step check (specificity, context, example, tier) is designed to be fast enough to run every time a weak output appears, not just on the worst cases.
Diagnosing the actual cause before re-asking converges on a good output far faster than repeated undirected regeneration.
Since specificity and context problems are far more common than genuine capability limits, checking them first avoids paying for a tier upgrade that wasn't the actual fix.
Diagnosing the root cause, not just patching one output, improves the underlying prompt or workflow so the same problem doesn't recur on the next similar task.
Check every gate before release
5 exam-pattern questions
Work through one question at a time, check the architecture, then move through the set.
An output comes back generic and doesn't reference any of the client's actual specifics, even though the prompt seemed reasonably clear. What should be checked first?
Frequently asked
How long should this diagnostic process actually take in practice?
A couple of minutes for most cases. Naming the problem and checking specificity and context is fast; it's meant to replace repeated blind regeneration, not add a lengthy new step to every task.
What if the output is weak in a way that doesn't fit any of the four checks cleanly?
Start with the most common cause, prompt specificity, then context, then example, in that order, even if the fit feels imperfect. Most real cases resolve within the first two checks; the order matters more than a perfect categorization.
Is it ever fine to just rewrite the output by hand instead of diagnosing?
For a true one-off, low-stakes task, sure, that's a reasonable shortcut. The problem is doing this as a default habit for a recurring task type, which means the same weak-output pattern keeps recurring instead of getting fixed at the root.
How do I know when a task genuinely needs a higher model tier versus better context?
Only after specificity, context, and an example have all been tried. If the output is still weak specifically on hard reasoning or nuanced judgment after those fixes, that's a real signal for tier escalation, not before.
Does this troubleshooting sequence apply to any Claude output, or just written deliverables?
It applies broadly, any Claude output that came back weaker than expected: an analysis, a summary, a recommendation, a draft. The same four checks, specificity, context, example, tier, apply regardless of the output's format.
What's the single most common actual cause of a weak Claude output in delivery work?
Missing or paraphrased context, the real source material wasn't provided, so Claude worked from a vague description instead. This shows up more often than either a vague prompt or a genuine model-capability limit.